Next
Papers near this one.
Walkthroughs
 6:36
Escaping the Diversity Trap in Robotic Manipulation via Anchor-Centric Adaptation
shares Learning from demonstration 7:13
FLEX-WAM: Flexible Block-Causal World-Action Models for Long-Horizon Imagination and Planning
2610.05483
shares VLA models
 6:28
Long-WAM: Scaling the Context of World-Action Models
2610.10528
shares VLA models
Short cuts
 0:45
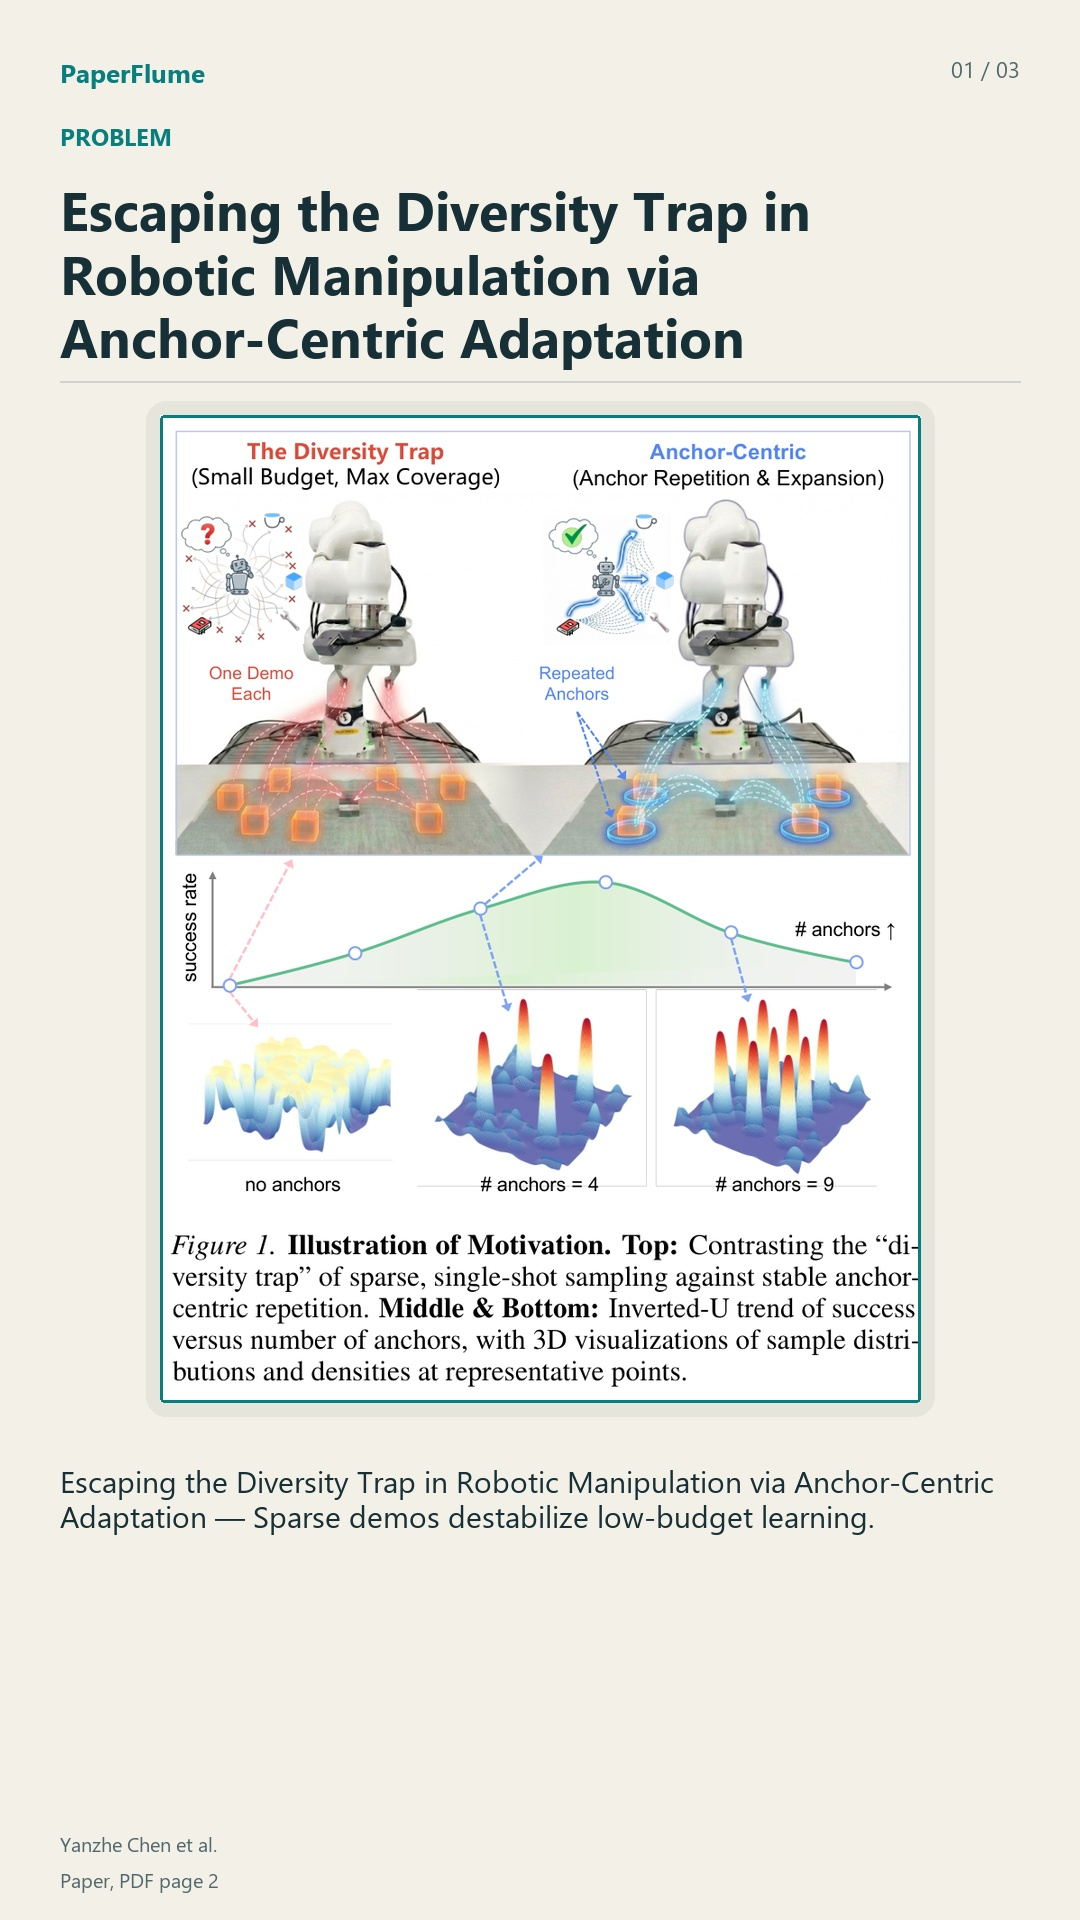
Escaping the Diversity Trap in Robotic Manipulation via Anchor-Centric Adaptation
shares Learning from demonstration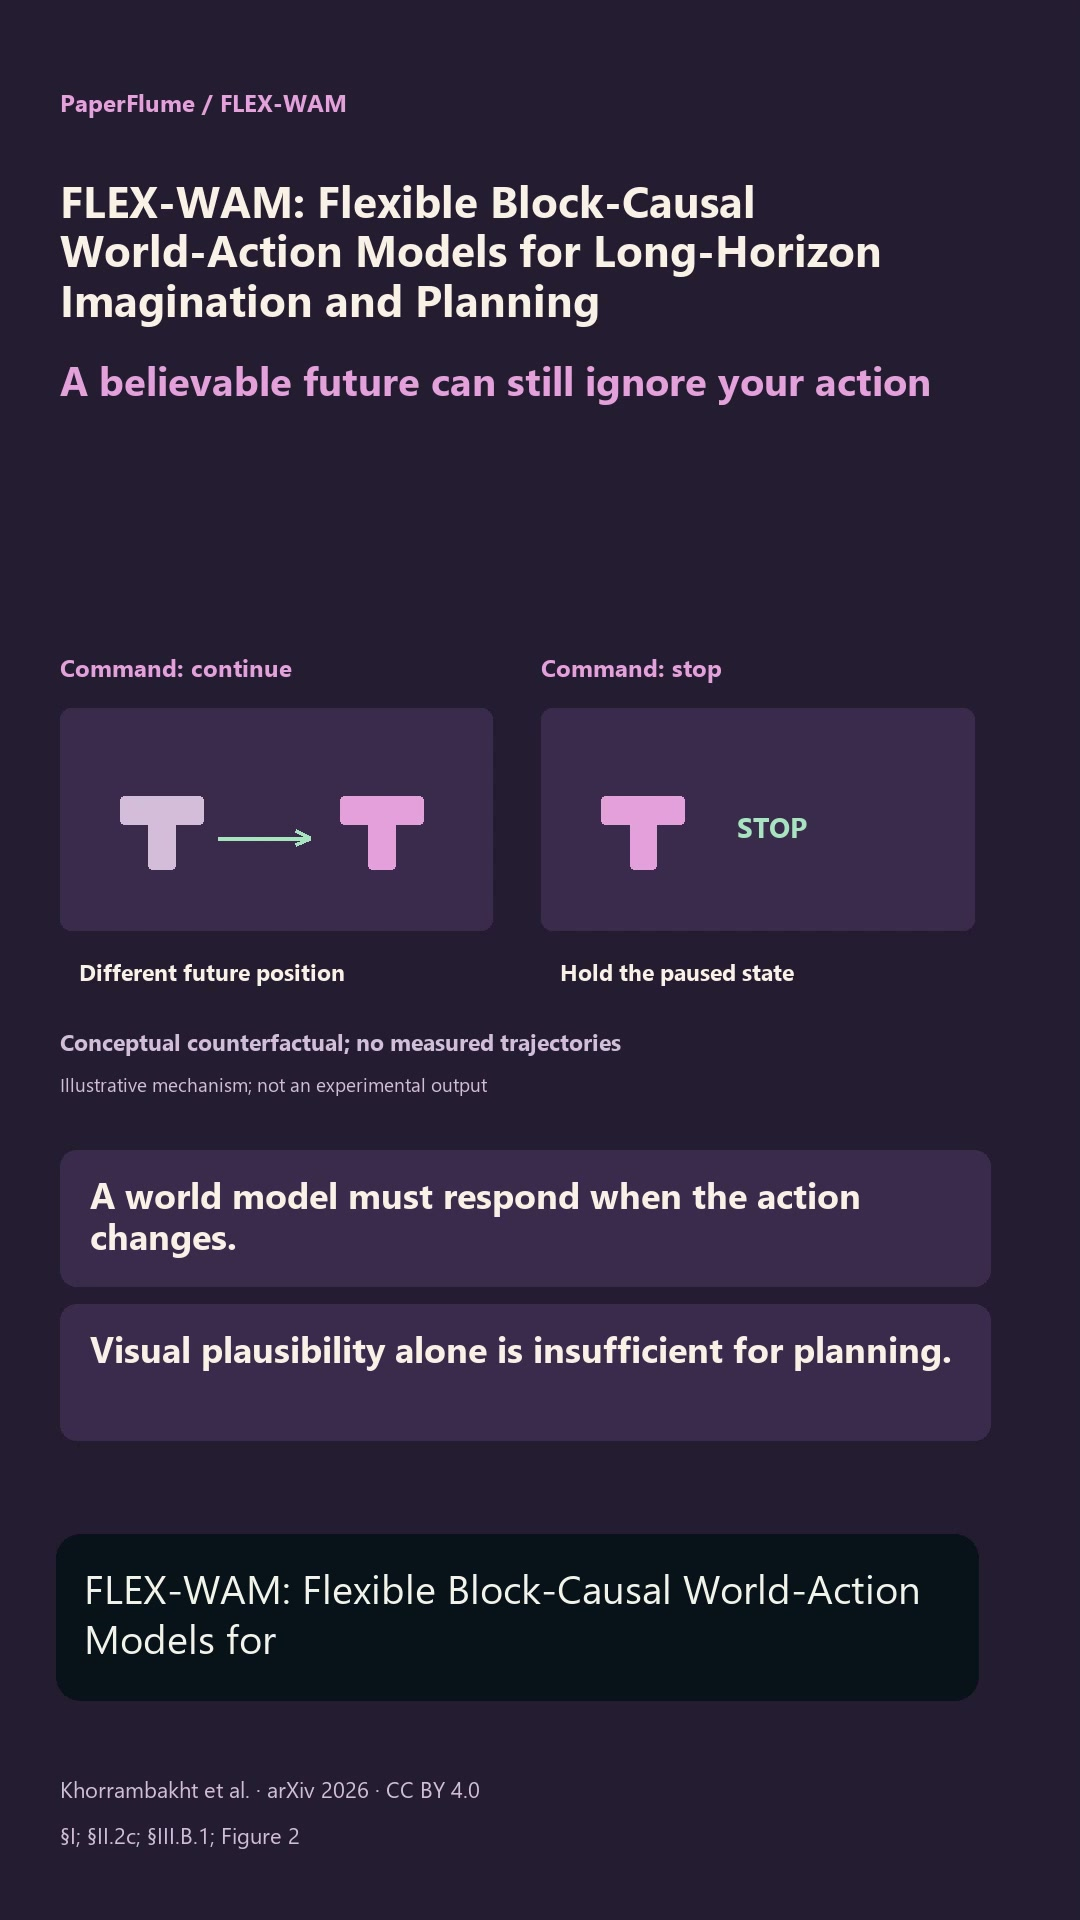 0:53
FLEX-WAM: Flexible Block-Causal World-Action Models for Long-Horizon Imagination and Planning
2610.05483
shares VLA models
 0:52
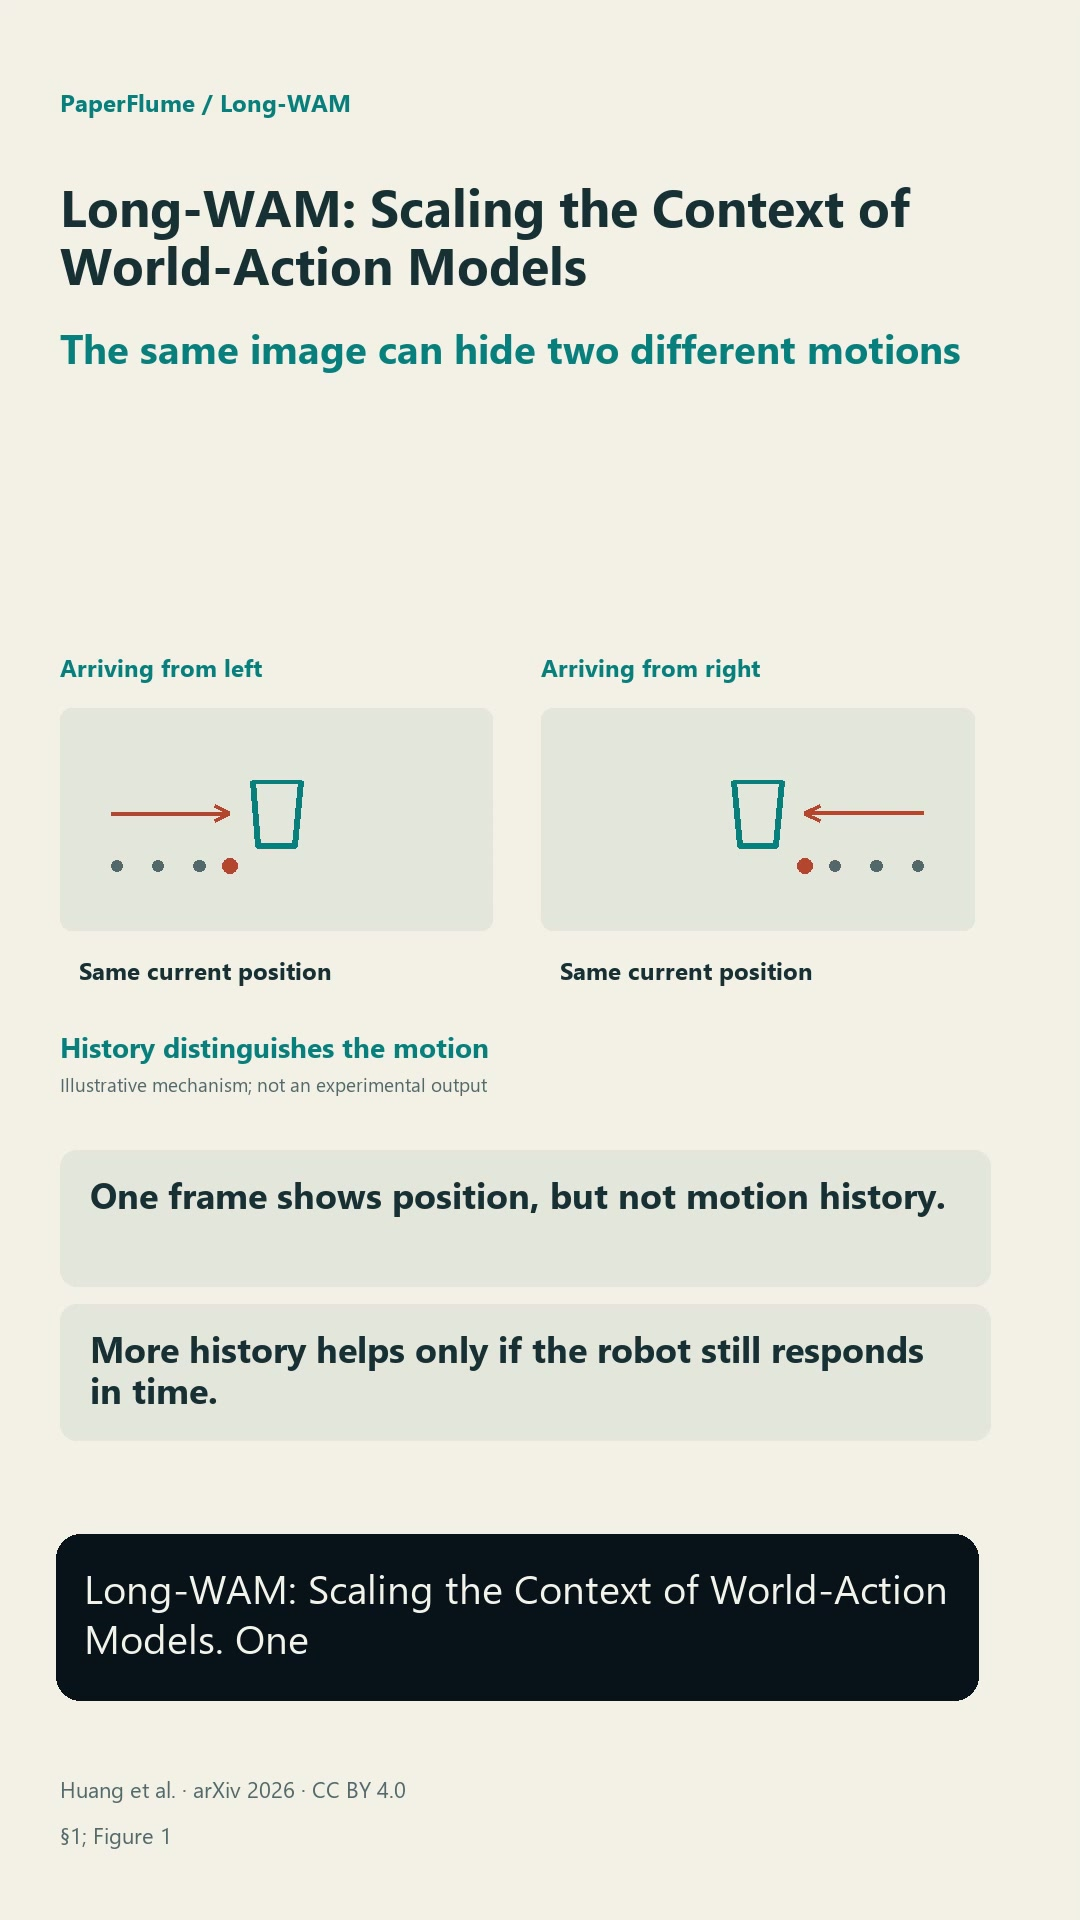
Long-WAM: Scaling the Context of World-Action Models
2610.10528
shares VLA models